hugging facemii-llm discord

MII-LLM an independent AI research community

We train, evaluate, develop and deploy AI systems. All our services are supported by Seeweb cloud provider. We ♥ Italy and open source.

Latest work

Small models. New possibilities.

Discover our newest model and the tools to build what comes next. Open research, made to be explored.

Small language model

Nesso3-0.4B-Agentic

Our latest bilingual Italian / English model for function calling and structured output. Built on Zagreus, Nesso3 learns a compact tool contract across thousands of tool schemas, with a focus on Italian tool use.

  • ~438M parameters
  • 32K context
  • Apache 2.0
Explore the model (opens in a new tab)
Training framework

Palingenesis

Research-informed fine-tuning with practical defaults. Memory-efficient training, native support for agentic data, and one configuration that scales from a single GPU to multi-node clusters.

  • Memory-efficient
  • Agentic training
  • Multi-node ready
Read the documentation (opens in a new tab)

Research in focus

From foundations to discovery.

Meet the models and experiments behind our community. Built to be studied, shared, and taken further.

Zagreus foundation model project artwork
02Open foundations for what comes next

Zagreus

Four bilingual foundation models, trained from scratch on around one trillion open-source tokens. Pairing English with Italian, Spanish, Portuguese, or French, Zagreus provides the foundation for Nesso—with open weights, configurations, and evaluations.

  • 4 bilingual models
  • ~1T training tokens
  • Trained from scratch
Artwork associated with the Maestrale Italian language model
03Italian language, at a larger scale

Maestrale

A 7-billion-parameter open model fine-tuned for fluent Italian across a wide range of domains. Maestrale brings together language generation, tool integration, structured JSON output, and reasoning capabilities.

  • 7B parameters
  • Italian generation
  • Tool integration

Built in the open

Open source contributions

Models, datasets, training tools, and benchmarks. Explore the research we share with the ML and AI community.

14 open contributions
Latest release

Small language model

Nesso3-0.4B-Agentic

Our latest compact bilingual Italian / English model for function calling and structured output, built for practical agentic workflows.

Explore on Hugging Face
(opens in a new tab)
Latest release

Training framework

Palingenesis

A memory-efficient fine-tuning framework with native support for agentic data, scaling from a single GPU to multi-node training.

Read the documentation
(opens in a new tab)

Code & research

Nesso Zagreus

Full technical report for the Zagreus & Nesso SLM families — from data pipeline and pre-training to post-training and evaluation — releasing 7 open bilingual Romance language models with fully reproducible configs.

View on GitHub
(opens in a new tab)

Code & research

Propaganda

Propaganda is an open-source initiative dedicated to assessing and generating political bias in Large Language Models (LLMs).

View on GitHub
(opens in a new tab)

Code & research

lm-evaluation-harness

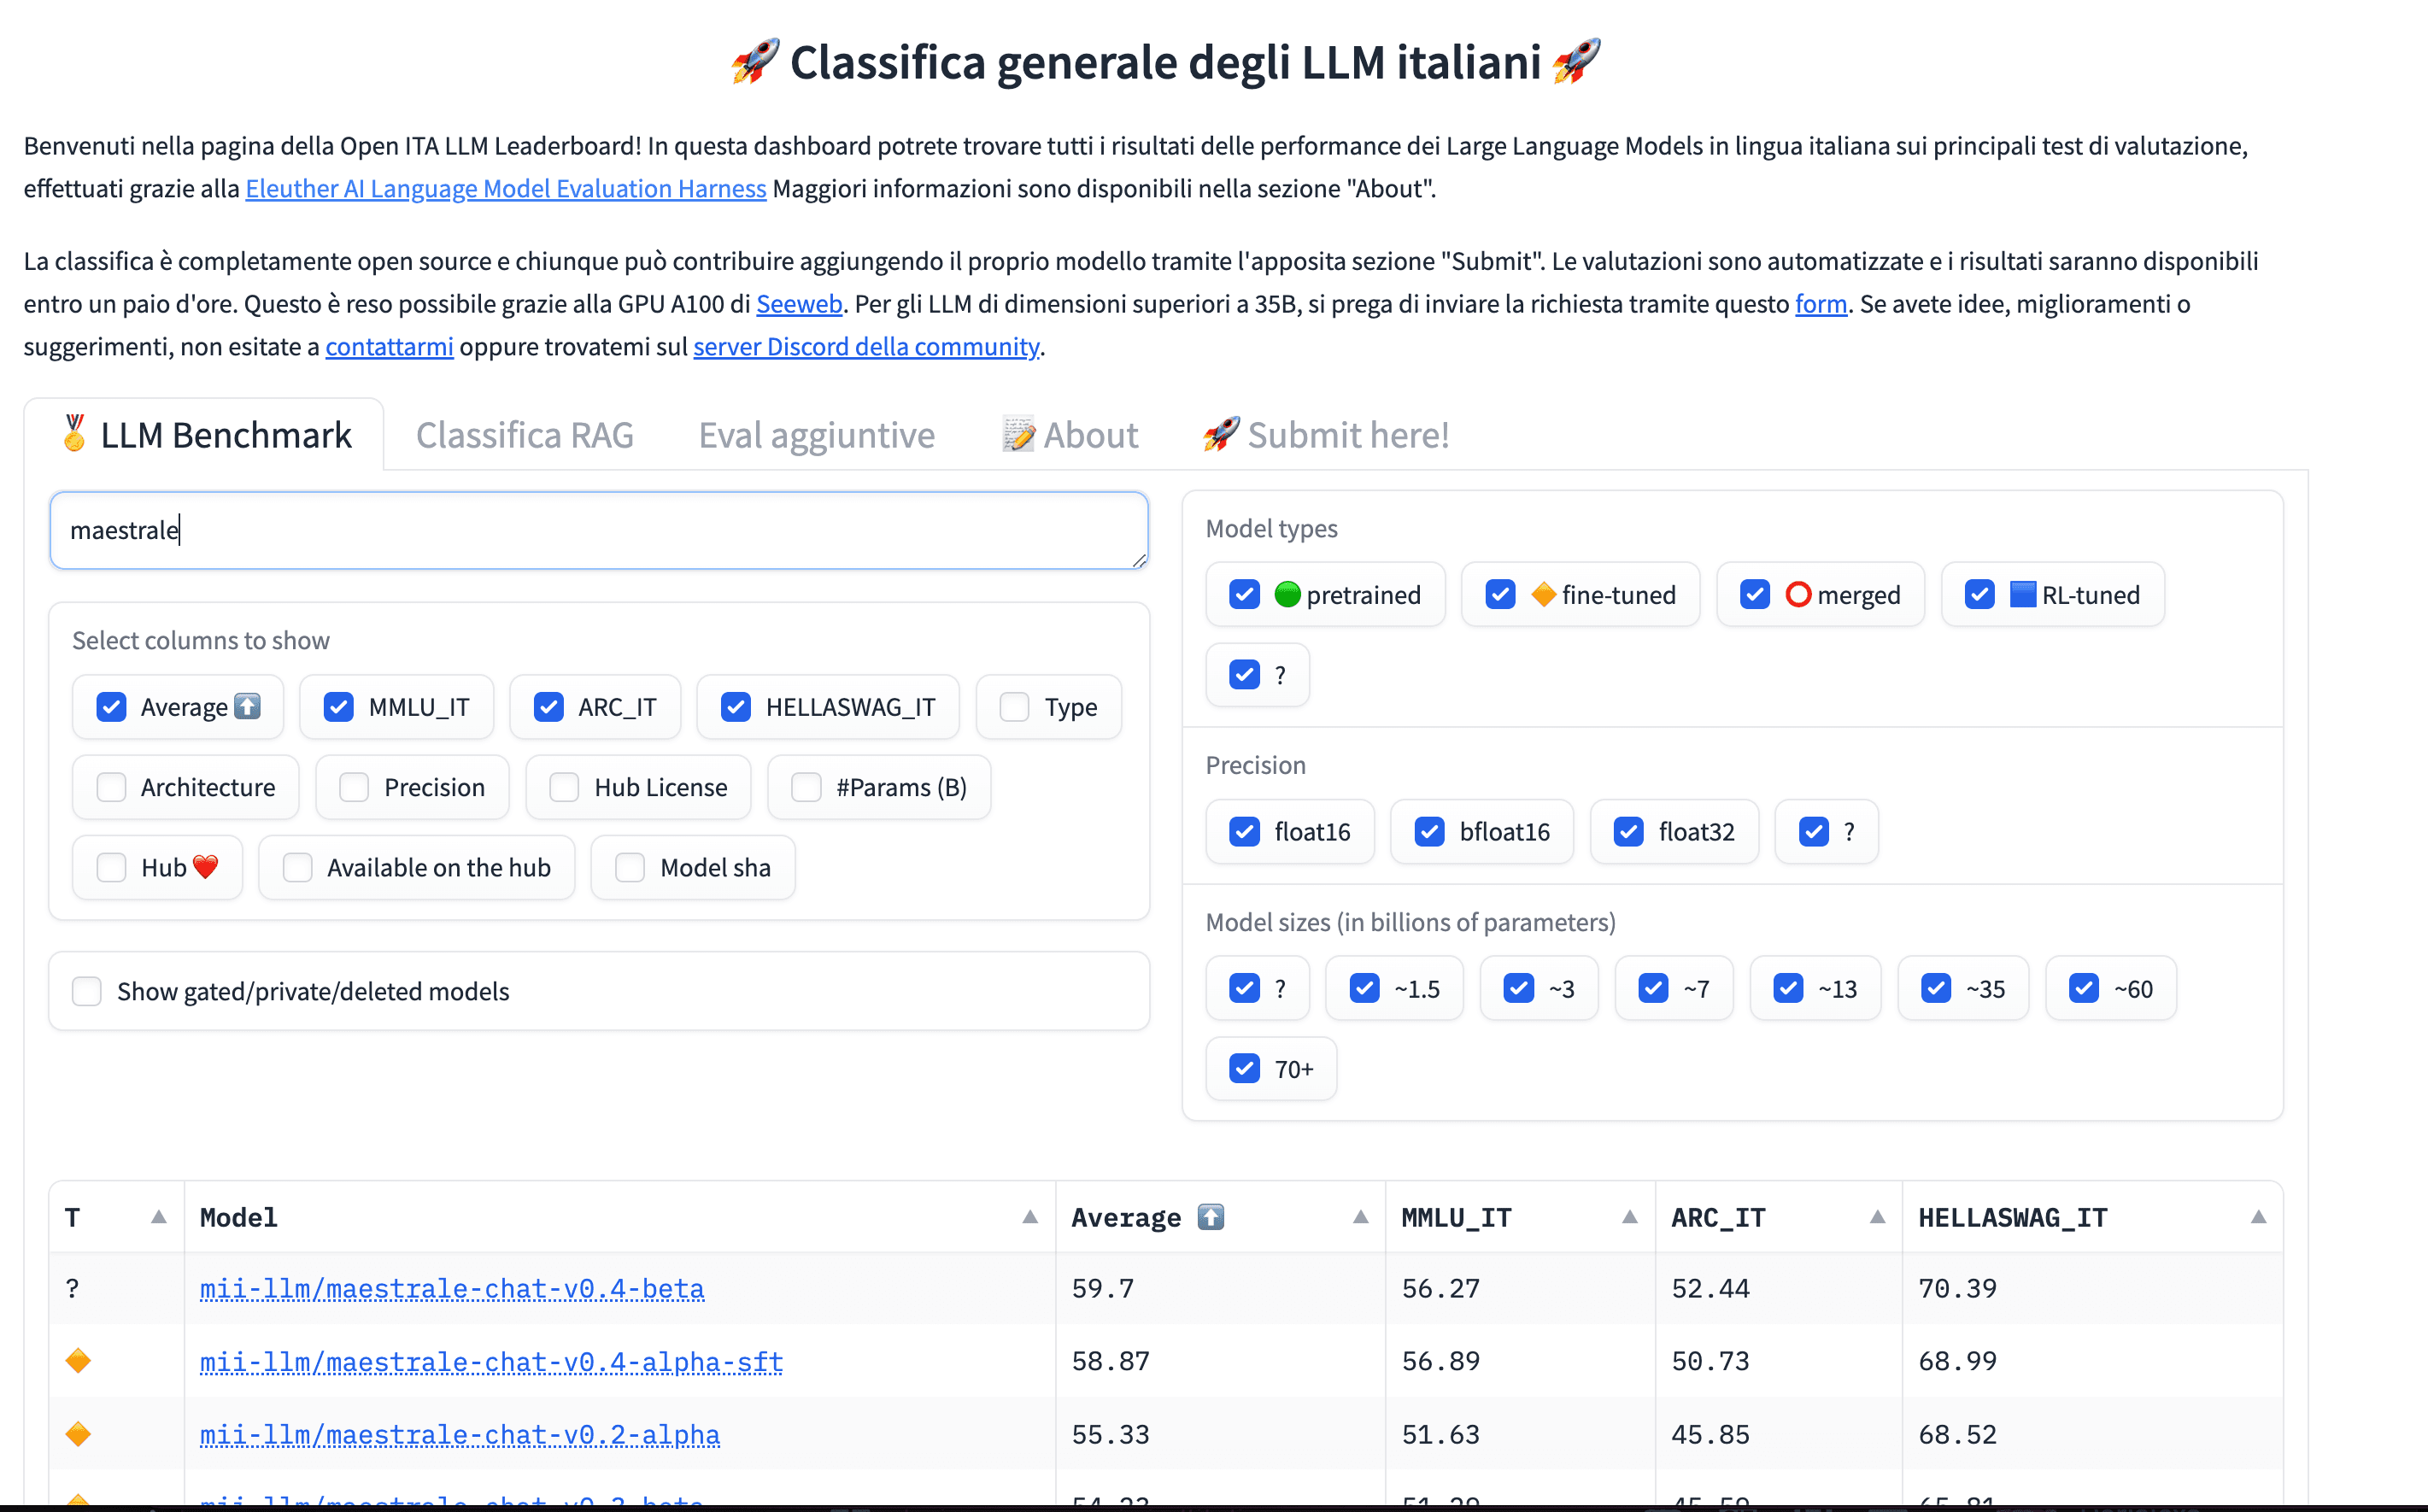
We contribute to add mmlu and arc_c evaluation benchmark for Italian based tasks. Our bechmarks are now used by many LLMs groups for evaluating Italian based LLMs

View on GitHub
(opens in a new tab)

Models & datasets

Zefiro trilogy

One of the first completely open source Italian model in three versions: continual pre-trained, SFT and DPO

Read the release

Models & datasets

Gazzetta Ufficiale

The entire corpus of the current Italian laws as an open source dataset

Explore on Hugging Face
(opens in a new tab)

Models & datasets

Ultrafeedback ITA

Translated version of the ultrafeedback dataset for SFT fine tuning

Explore on Hugging Face
(opens in a new tab)

Models & datasets

Ultrafeedback binarized ITA

Translated version eng to ita of the popular ultrafeedback binarized dataset for DPO fine tuning.

Explore on Hugging Face
(opens in a new tab)

Models & datasets

Usenet conversations

The biggest dataset of real conversations in the Italian language from usenet

Explore on Hugging Face
(opens in a new tab)

Code & research

mmlu-pro

We tranlated the mmlu-pro dataset to Italian and contributed to integrate into the lm-eval command for evaluating Italian LLM on difficult tasks

View on GitHub
(opens in a new tab)

Models & datasets

Maestrale series

A series of open source LLMs a fine tuned versions of mistral 7 Billion for producing Italian

Explore on Hugging Face
(opens in a new tab)

Models & datasets

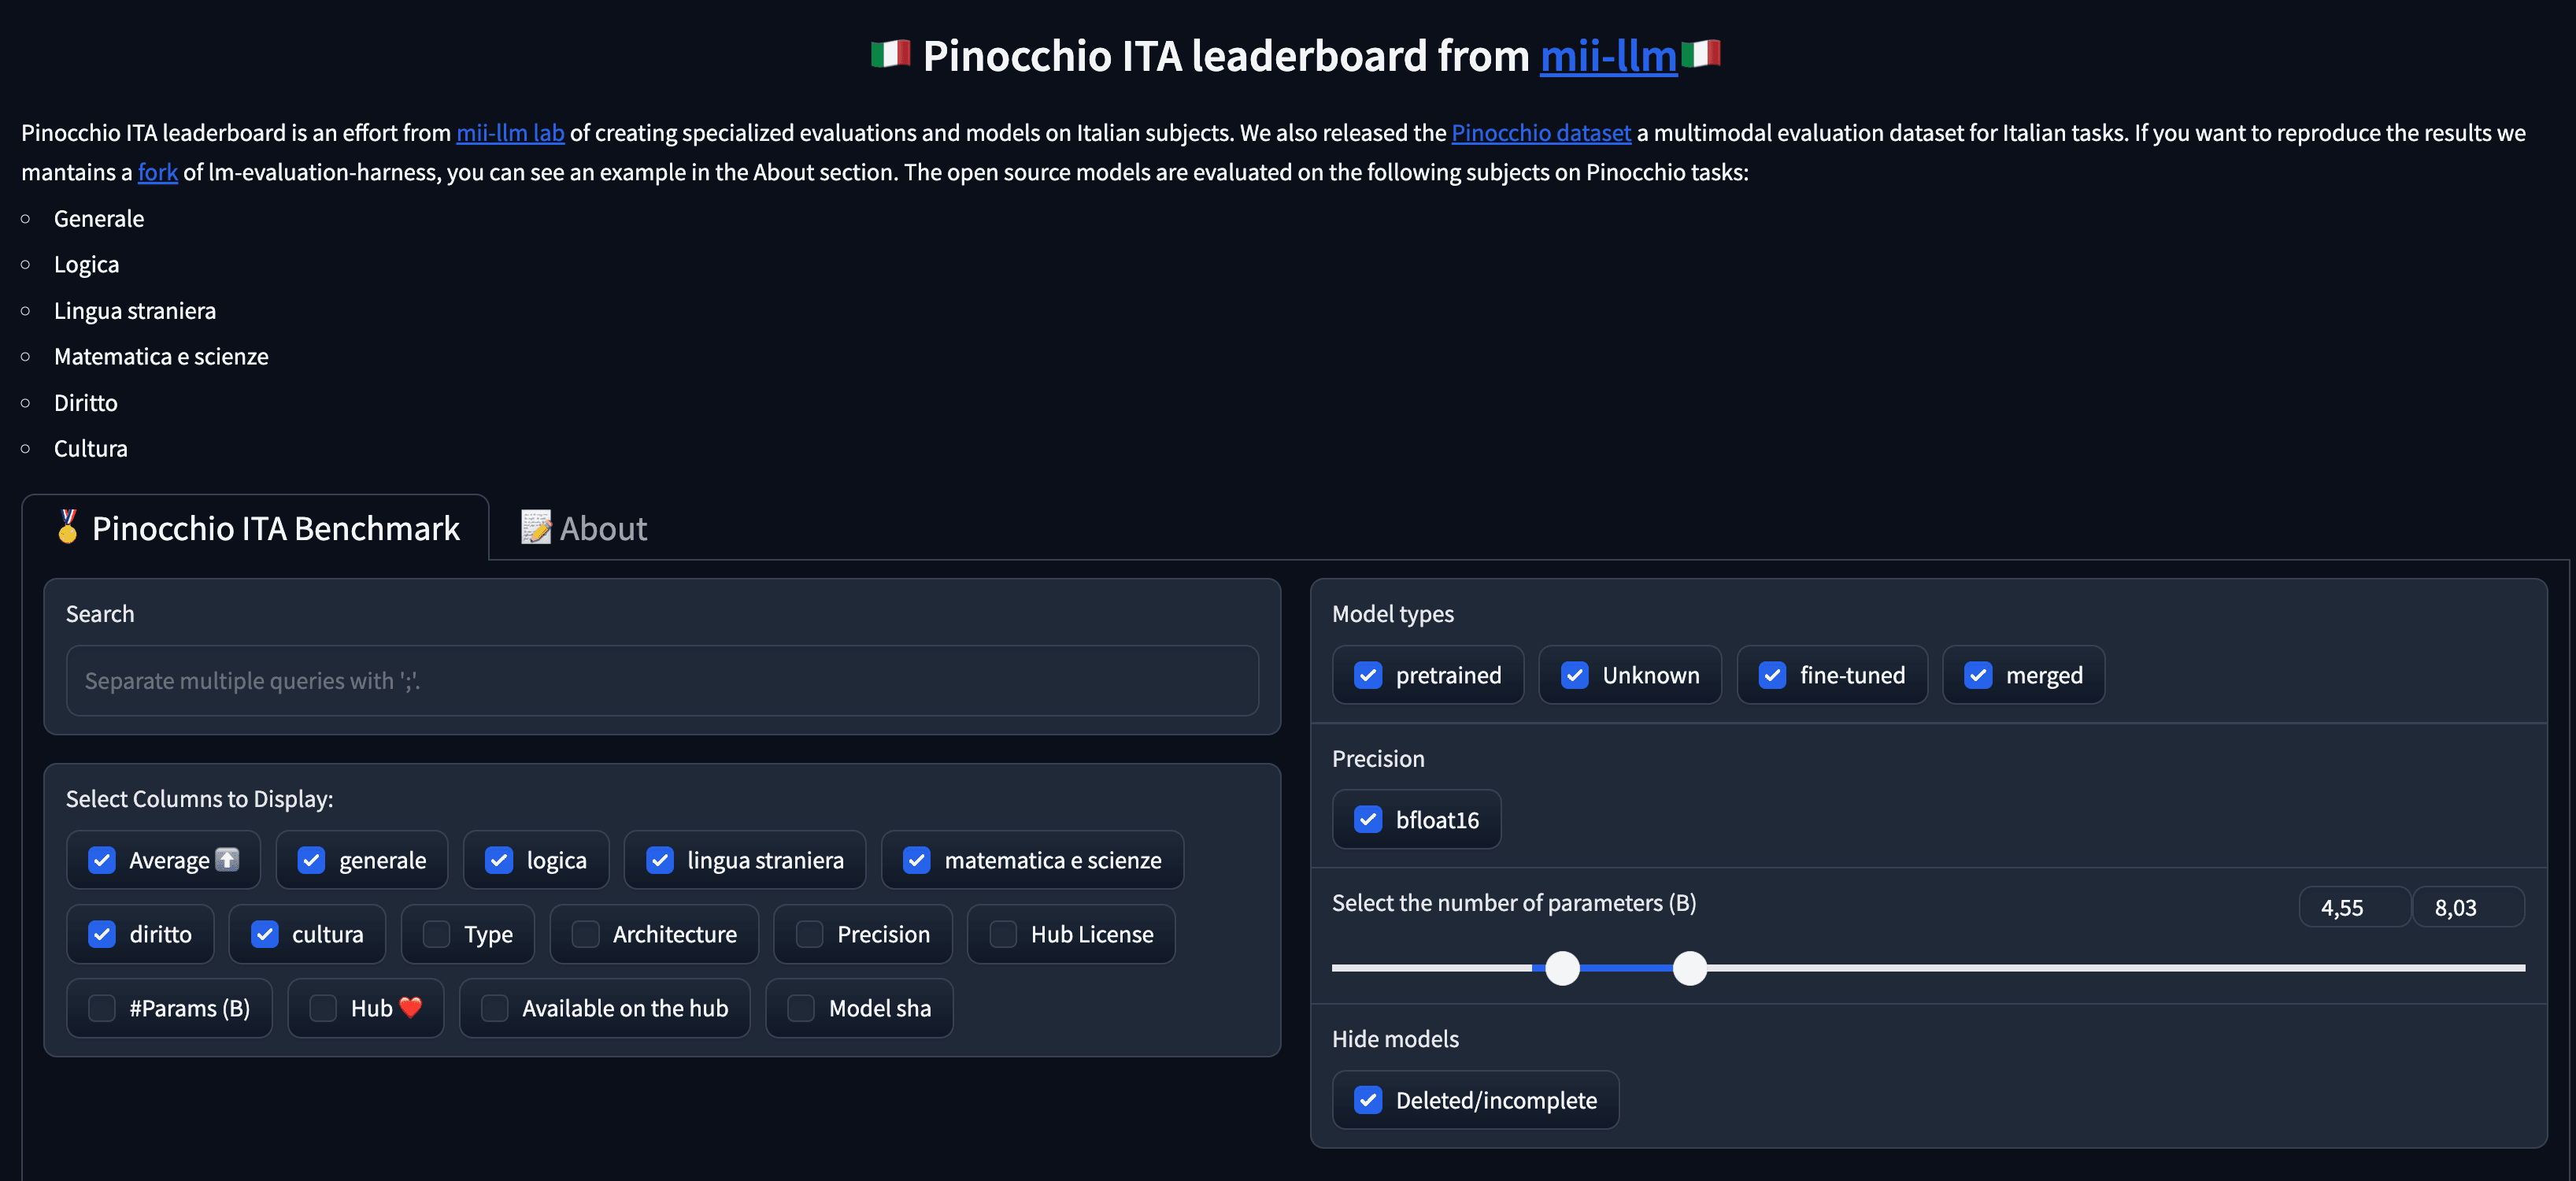
Pinocchio Eval dataset

A multimodal and text dataset for evaluating LLMs on Italian tasks

Explore on Hugging Face
(opens in a new tab)

Code & research

lm-evaluation-harness fork

A fork of lm-evaluation-harness with Italian specific tasks: mmlu arc-c hellaswag pinocchio-law, pinocchio-logic, pinocchio-math and reasoning like mmlu-pro-ita

View on GitHub
(opens in a new tab)